Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
Facebook introduces AI Sandbox
 News
Turn Text into Music
 News
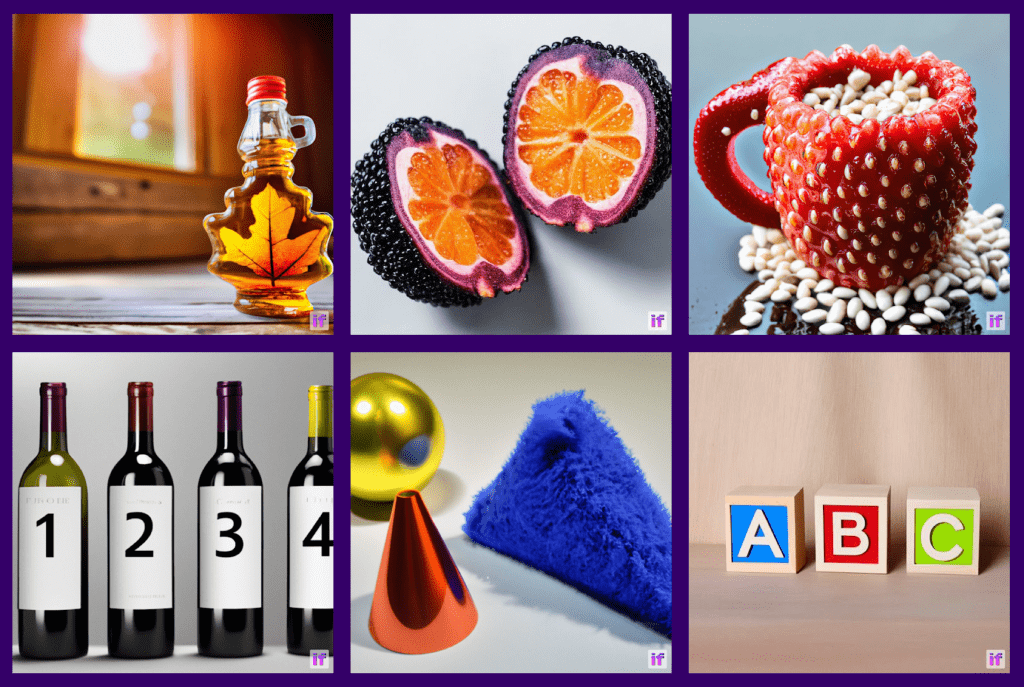
DeepFloyd IF, a powerful text-to-image model that can smartly integrate text into images
 News
Adobe introduces Firefly, a family of new creative generative AI
 Papers
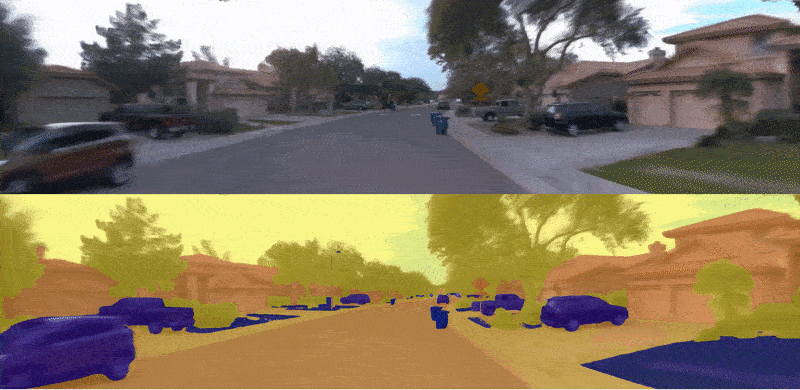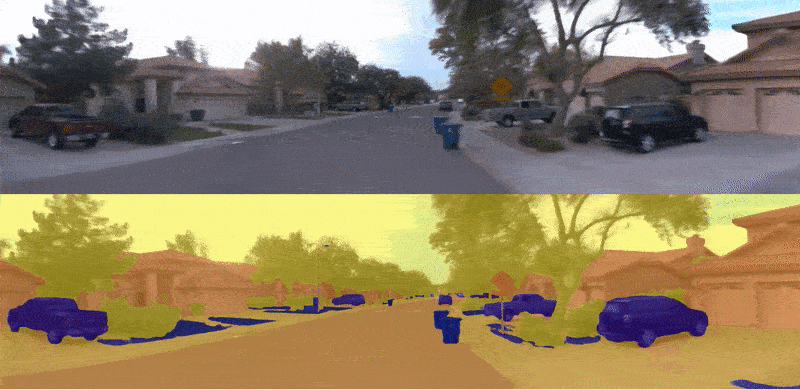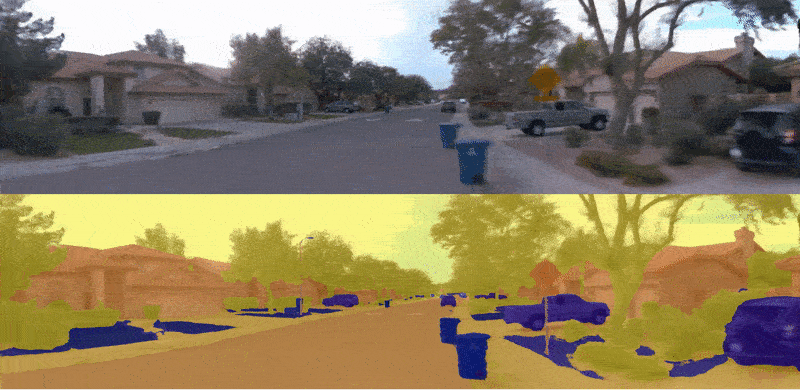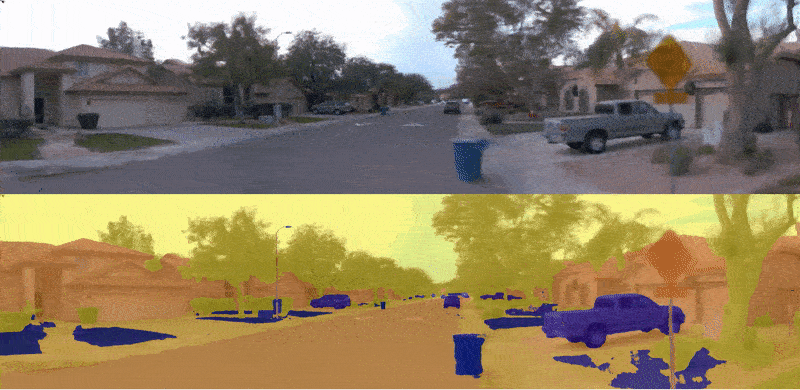
S-NeRF: Neural Radiance Fields for Street Views
 News
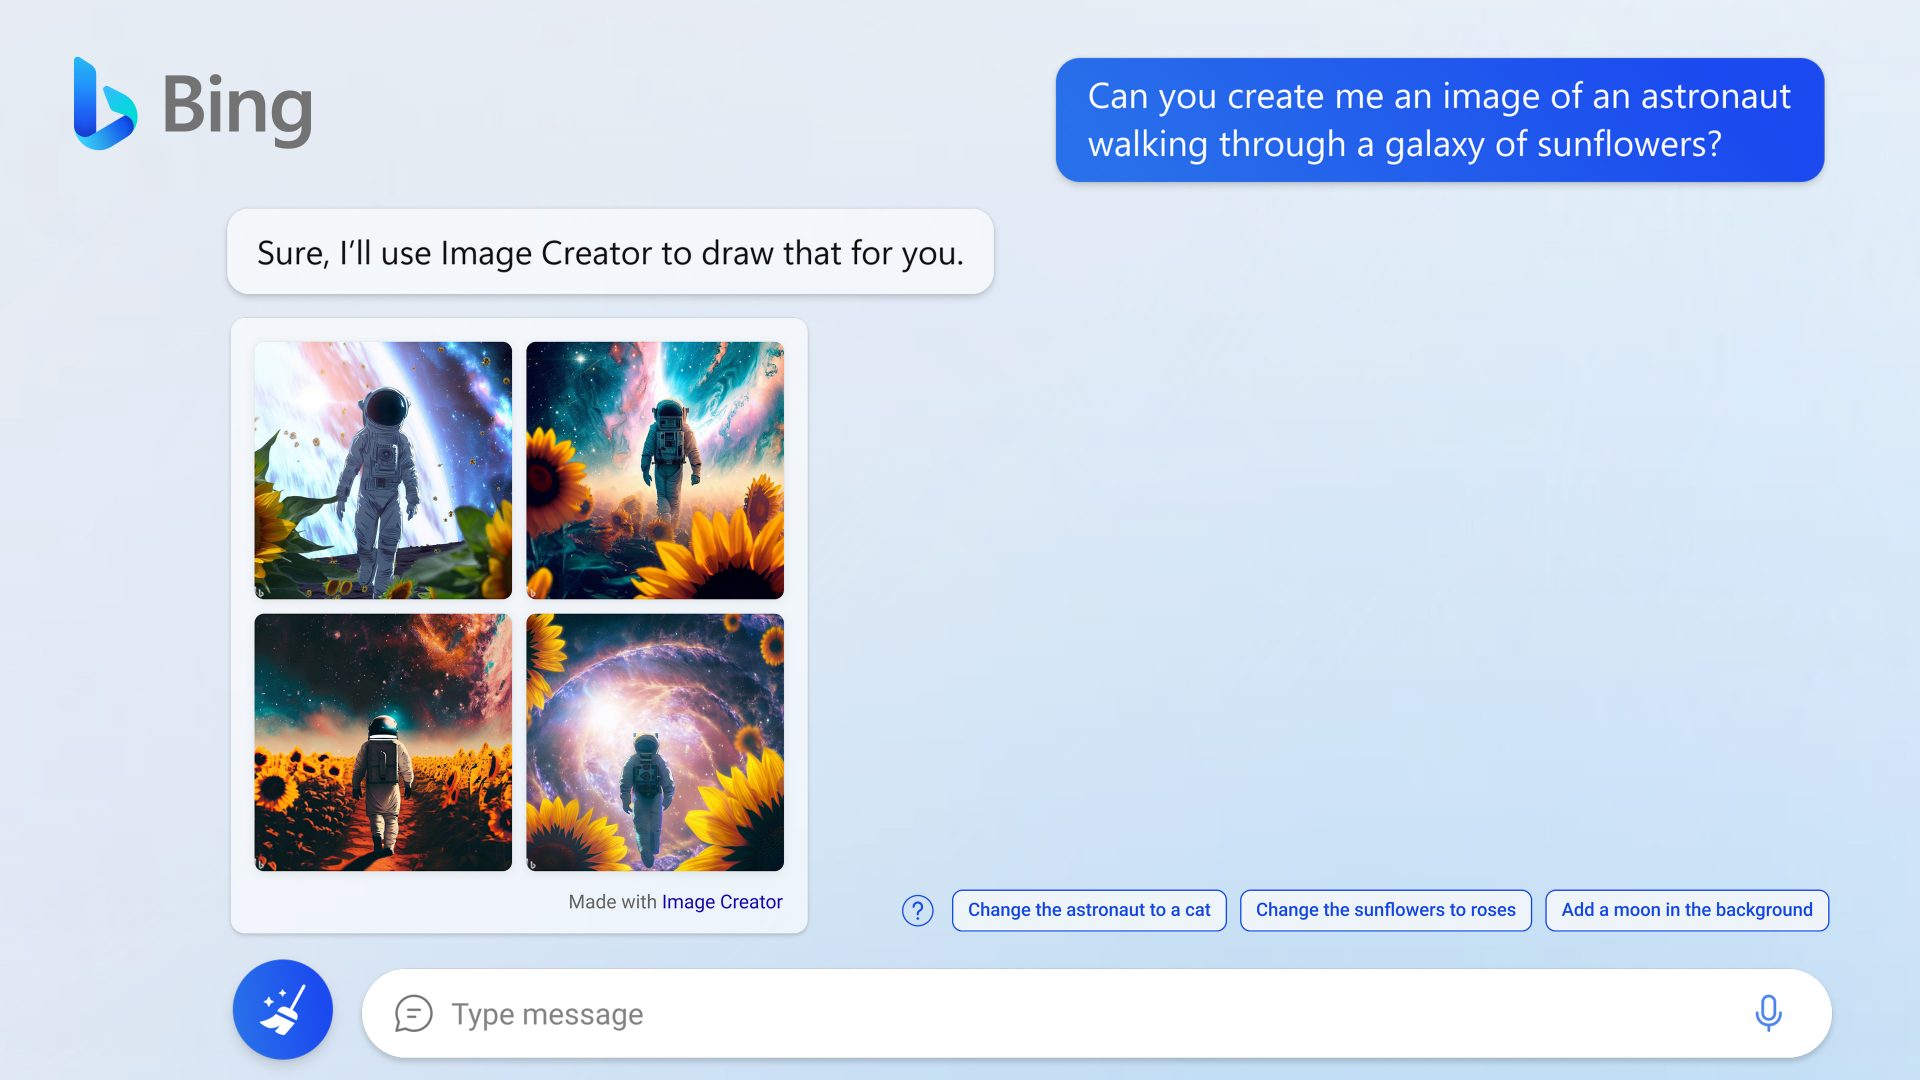
The new Bing comes with Bing Image Creator
 Papers
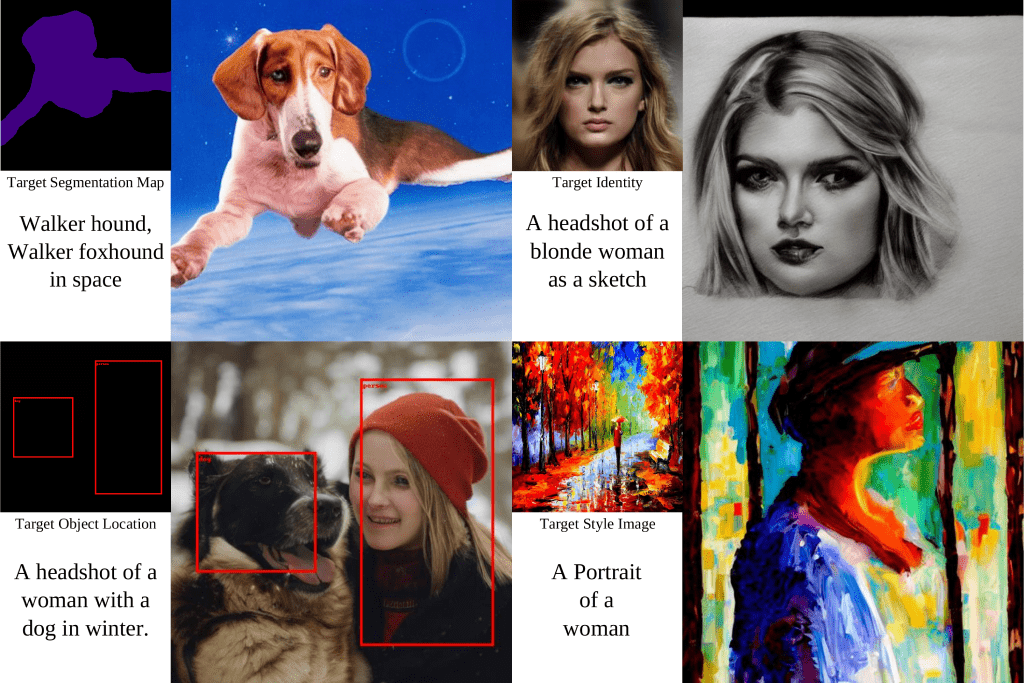
Universal Guidance for Diffusion Models
 News
The long-awaited release of multimodal GPT-4 will take place next week
 News
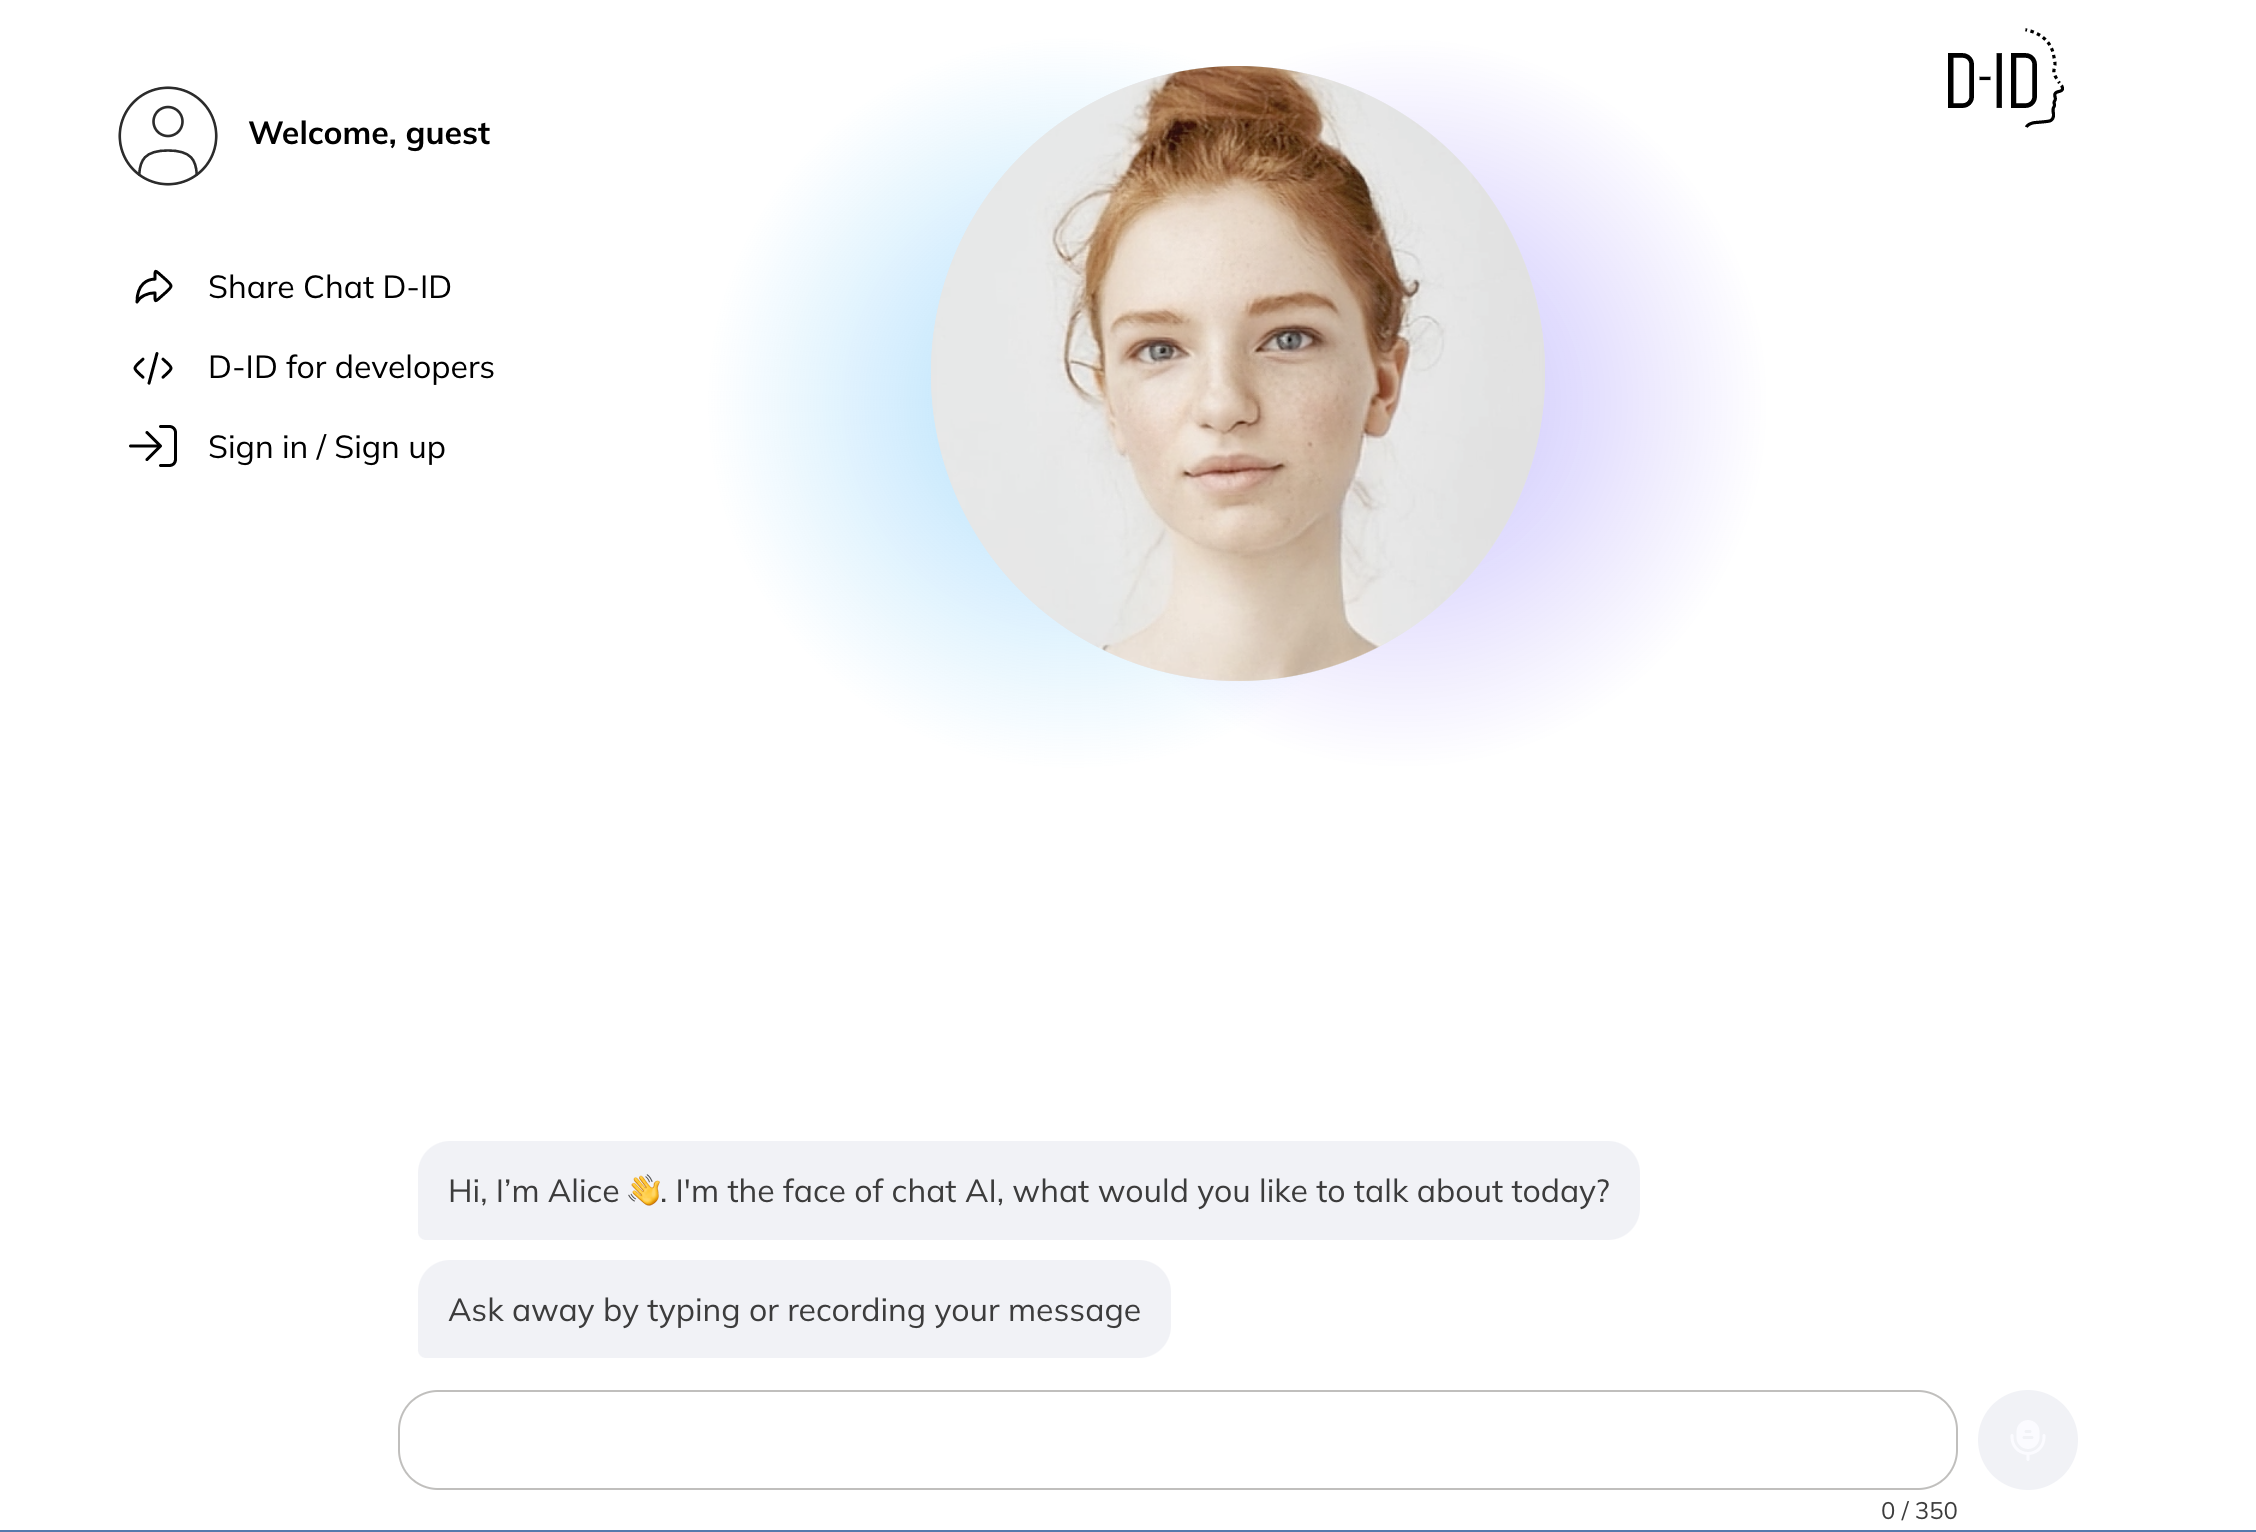
chat.D-ID enables anyone to talk face to face with AI
 Papers
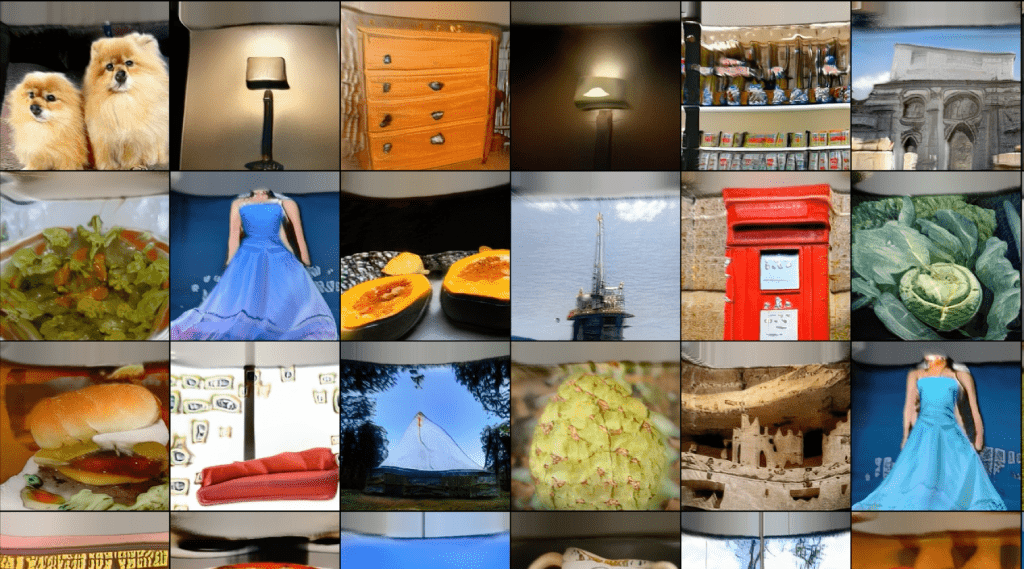
3D Generation on ImageNet
 Papers
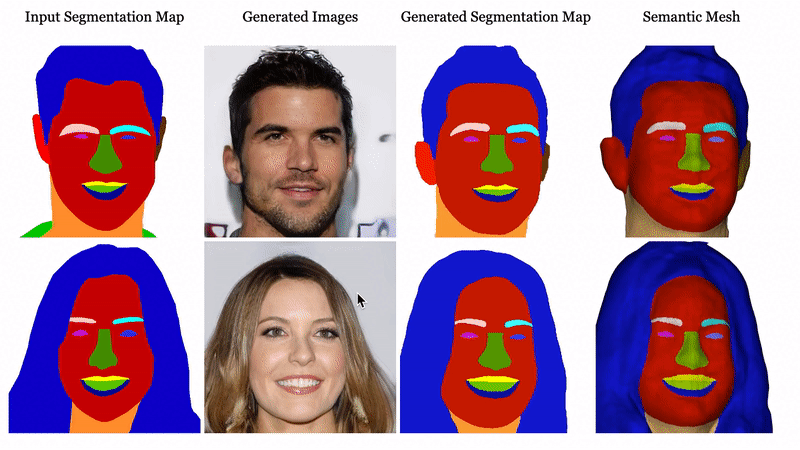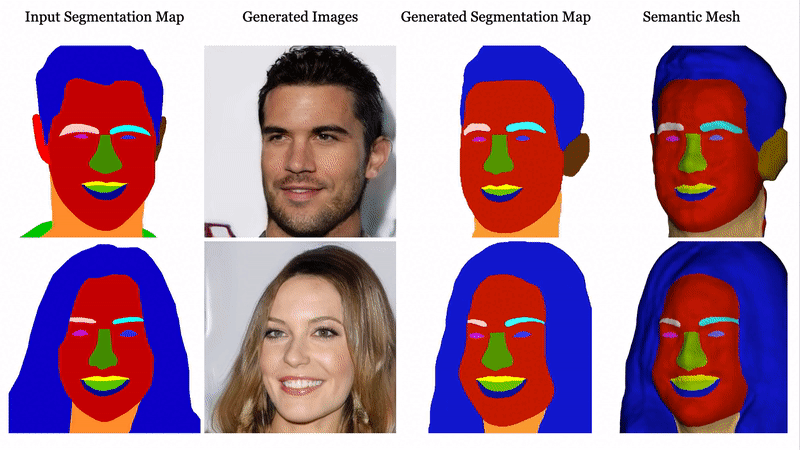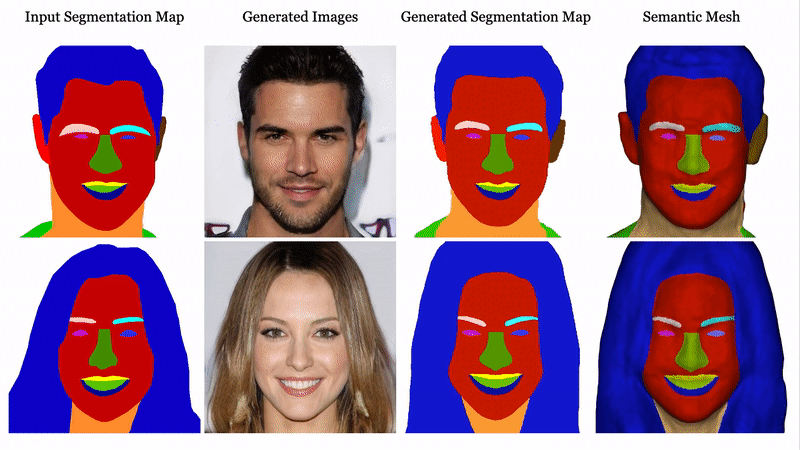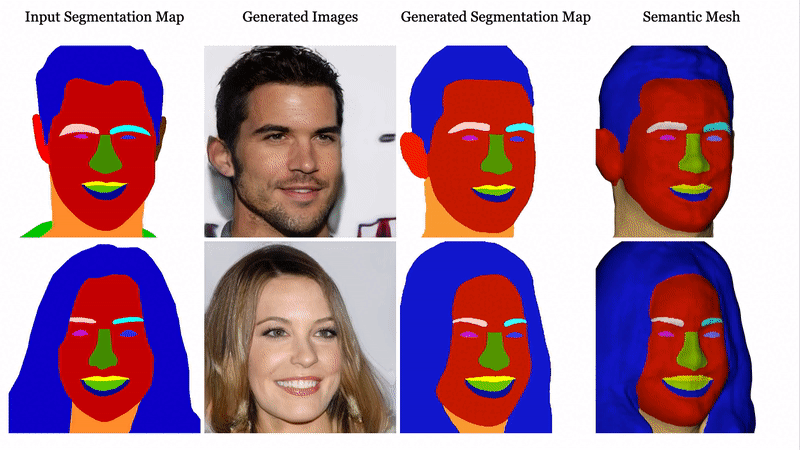
3D-aware Conditional Image Synthesis
 Papers
SinMDM: Single Motion Diffusion