Multimodal AI
Multimodal AI systems work with more than one kind of input or output, such as text, images, audio, or video.
Follow model and application developments in speech, image, and video. Coverage looks at generation, understanding, media formats, and practical developer access.
Latest coverage
Articles
 News
AMD presents Nitro-P for pixel-space text-to-image generation
 News
Google rolls out Genie 4 to eligible AI Ultra subscribers
 News
OpenAI rolls out Live Dictation across all ChatGPT plans
 News
Snowflake adds generally available TwelveLabs video AI to Cortex functions
 News
Stretto deploys Amazon Nova voice agent for bankruptcy intake
 News
Apple researchers detail split-and-scale method for higher-capacity latent 3D
 News
Reson8 releases Rumble-2-Flash speech model under Apache 2.0
 News
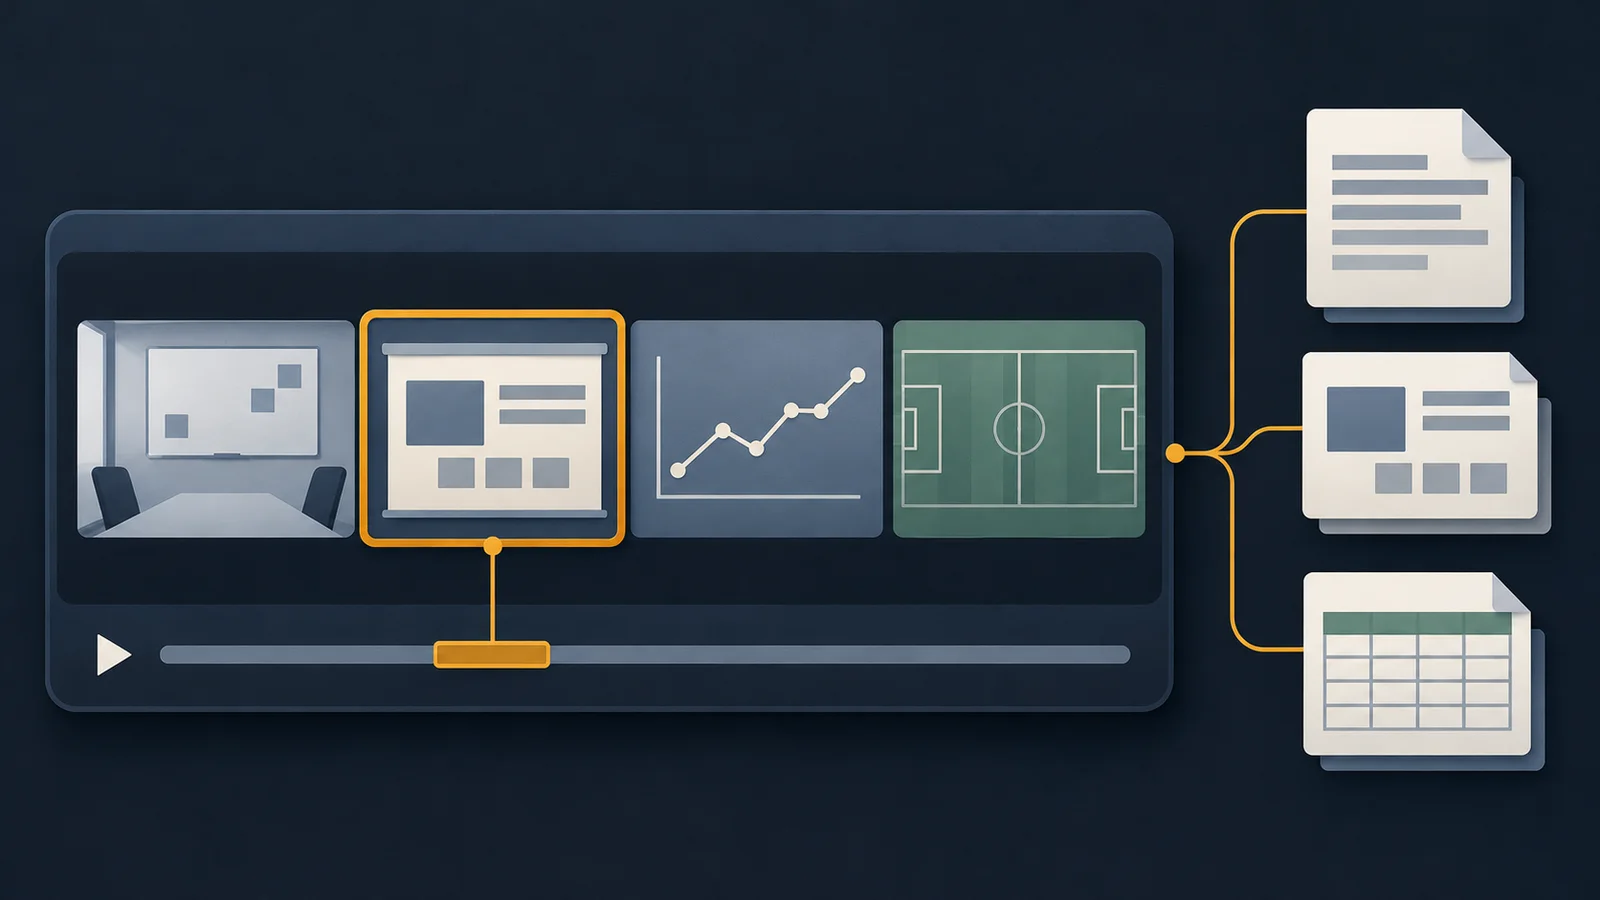
Cohere previews timestamped video search in Compass
 News
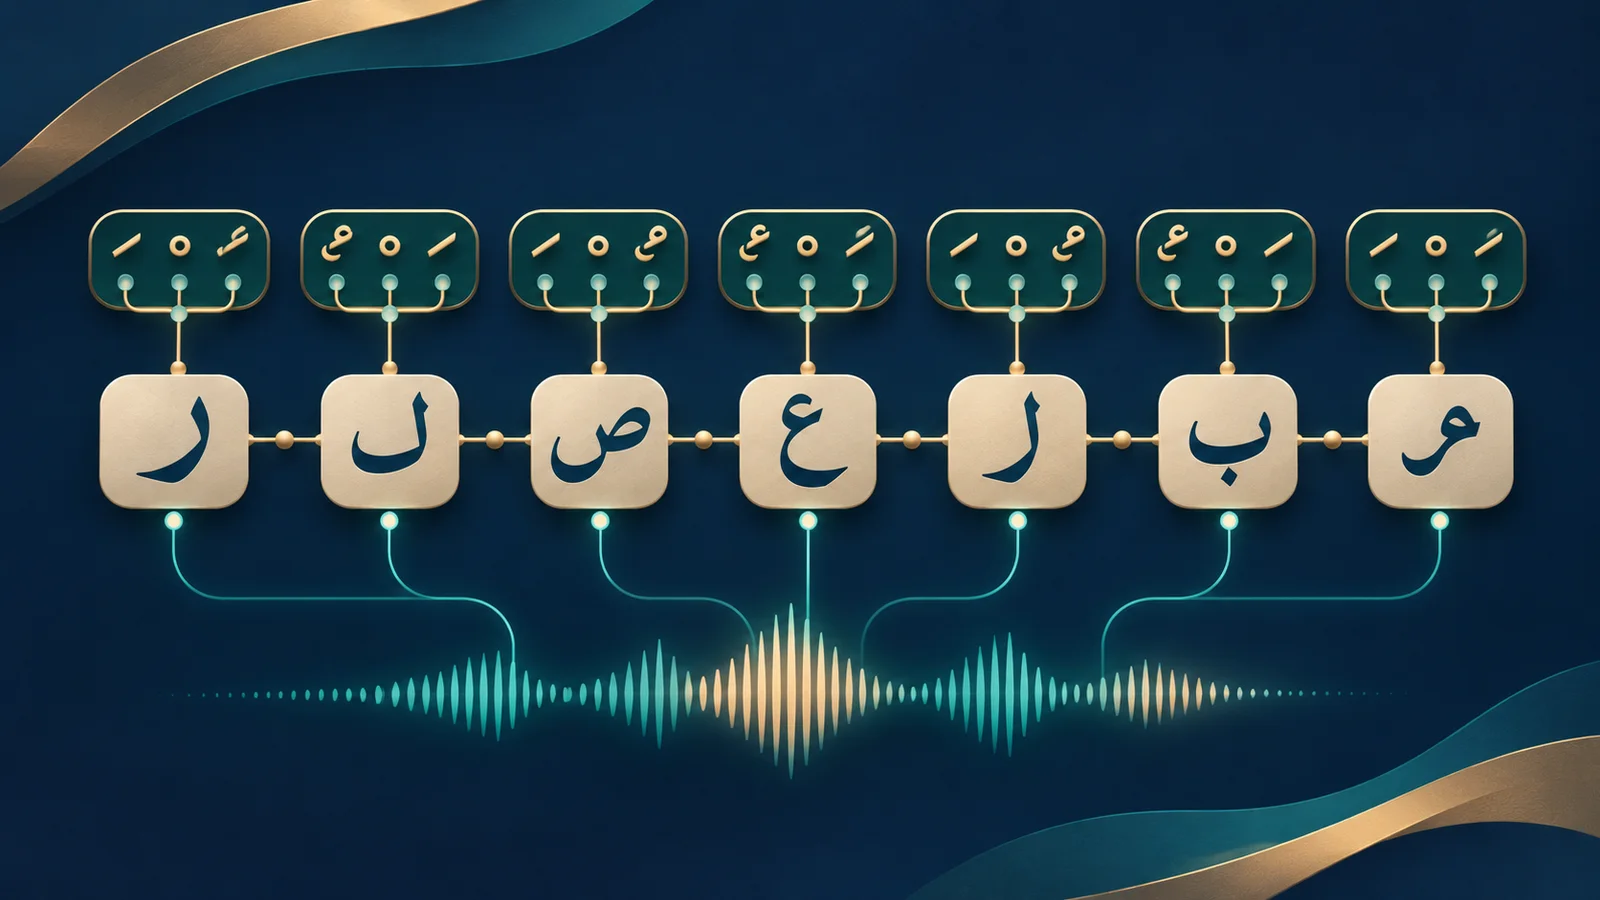
MBZUAI researchers constrain speech decoding to restore Arabic diacritics
 News
Alibaba launches Qwen4-Max multimodal model across six regions
 News
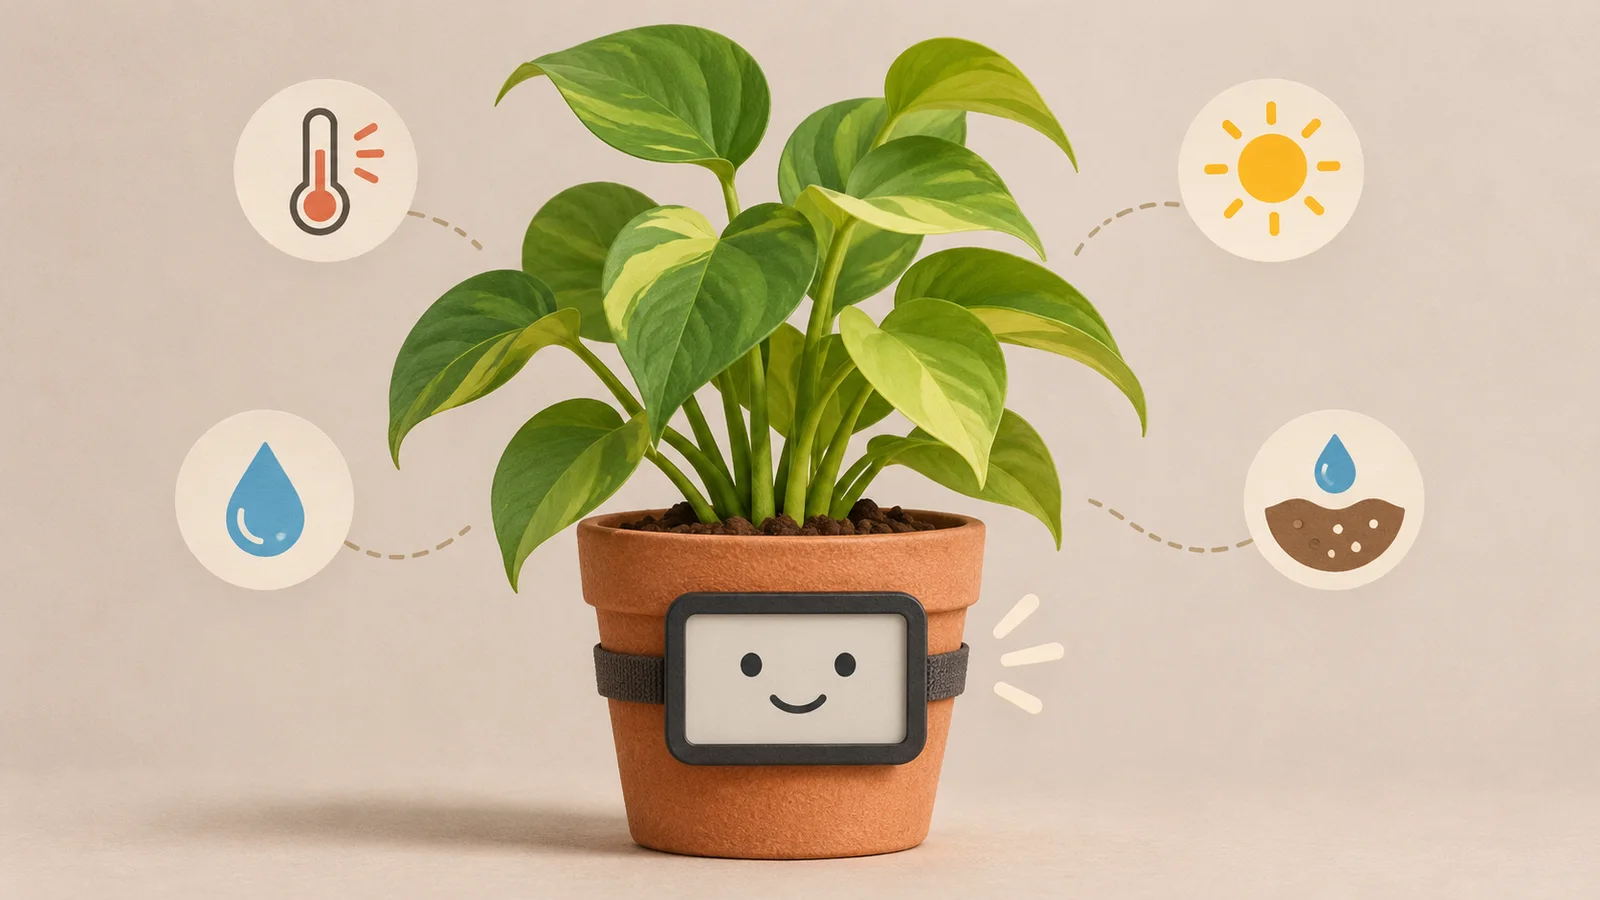
CMU researchers give everyday objects expressive OATs avatars
 News
World Labs releases Frameboy preview for real-time Atlas exploration