Meituan open-sources LongCat-2.0, a 1.6-trillion-parameter coding model trained on Chinese chips
Meituan released LongCat-2.0 under the MIT license on June 30, 2026, a 1.6-trillion-parameter coding model trained on roughly 50,000 Chinese ASICs that scores 59.5 on SWE-bench Pro.
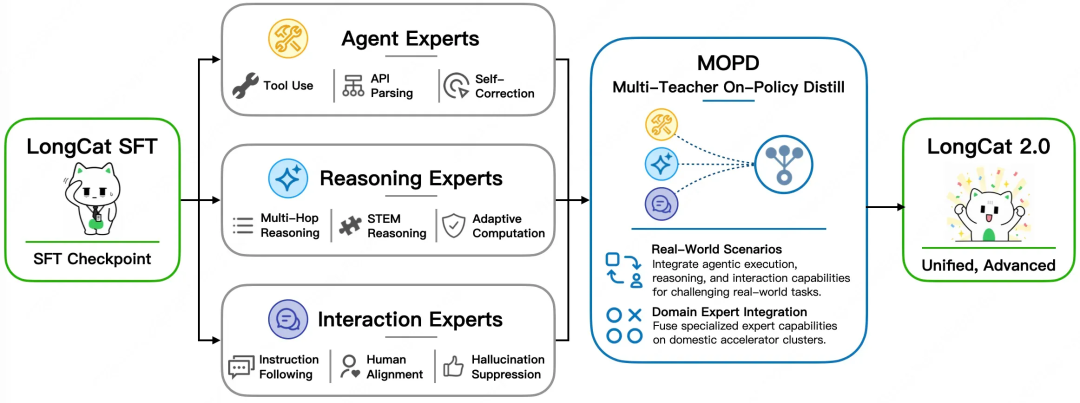
Meituan open-sourced LongCat-2.0 on June 30, 2026 under the MIT license, a 1.6-trillion-parameter mixture-of-experts model the company says was trained entirely on roughly 50,000 domestic Chinese ASIC chips. On SWE-bench Pro, a coding benchmark, it scores 59.5, edging out OpenAI’s GPT-5.5 at 58.6. The LongCat-2.0 release marks one of the first near-frontier agentic coding models built without Western accelerators.
The hardware story is the news here. Most frontier models train on Nvidia GPUs; Meituan, the Chinese food-delivery and services giant, says its run used domestic silicon, and the training communications reportedly rely on Huawei’s Collective Communication Library, pointing to Huawei hardware underneath. That makes LongCat-2.0 a concrete data point on how far Chinese chips have closed the gap under US export controls.
Architecturally, the model is a mixture-of-experts design that activates 33 billion to 56 billion parameters per token and carries a 1-million-token context window. Meituan says pretraining covered more than 30 trillion tokens across Chinese, English, multilingual and code data. The company credits three techniques it calls LongCat Sparse Attention, zero-computation expert routing, and Multi-Teacher On-Policy Distillation.
The model had already been circulating. Before the official launch, it ran globally on the OpenRouter marketplace under the codename “Owl Alpha” and ranked among the platform’s top models by call volume, a signal of real developer demand rather than benchmark theater. Weights are now hosted on Hugging Face under the meituan-longcat organization.
The benchmark figures come from Meituan and have not been independently verified; a one-point margin over GPT-5.5 on SWE-bench Pro is within the range where prompt and harness differences can swing results. Meituan also reported 77.3 on SWE-bench Multilingual and 79.9 on BrowseComp.

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
