DeepSeek adds vision to its Flash model, claims narrowing gap with Claude Opus
DeepSeek released DeepSeek-V4-Flash-Vision-Exp, an experimental multimodal model, on its API platform, claiming benchmark results approaching Anthropic's Claude Opus 4.8.
DeepSeek has released DeepSeek-V4-Flash-Vision-Exp, an experimental multimodal model that adds image understanding to its Flash line, live on the DeepSeek API Platform as of Aug. 21.
The model keeps the text capabilities of DeepSeek-V4-Flash — agentic tasks, reasoning and world knowledge — and layers on the ability to read images, aimed at document and chart analysis, visual question answering and multimodal agent workflows.
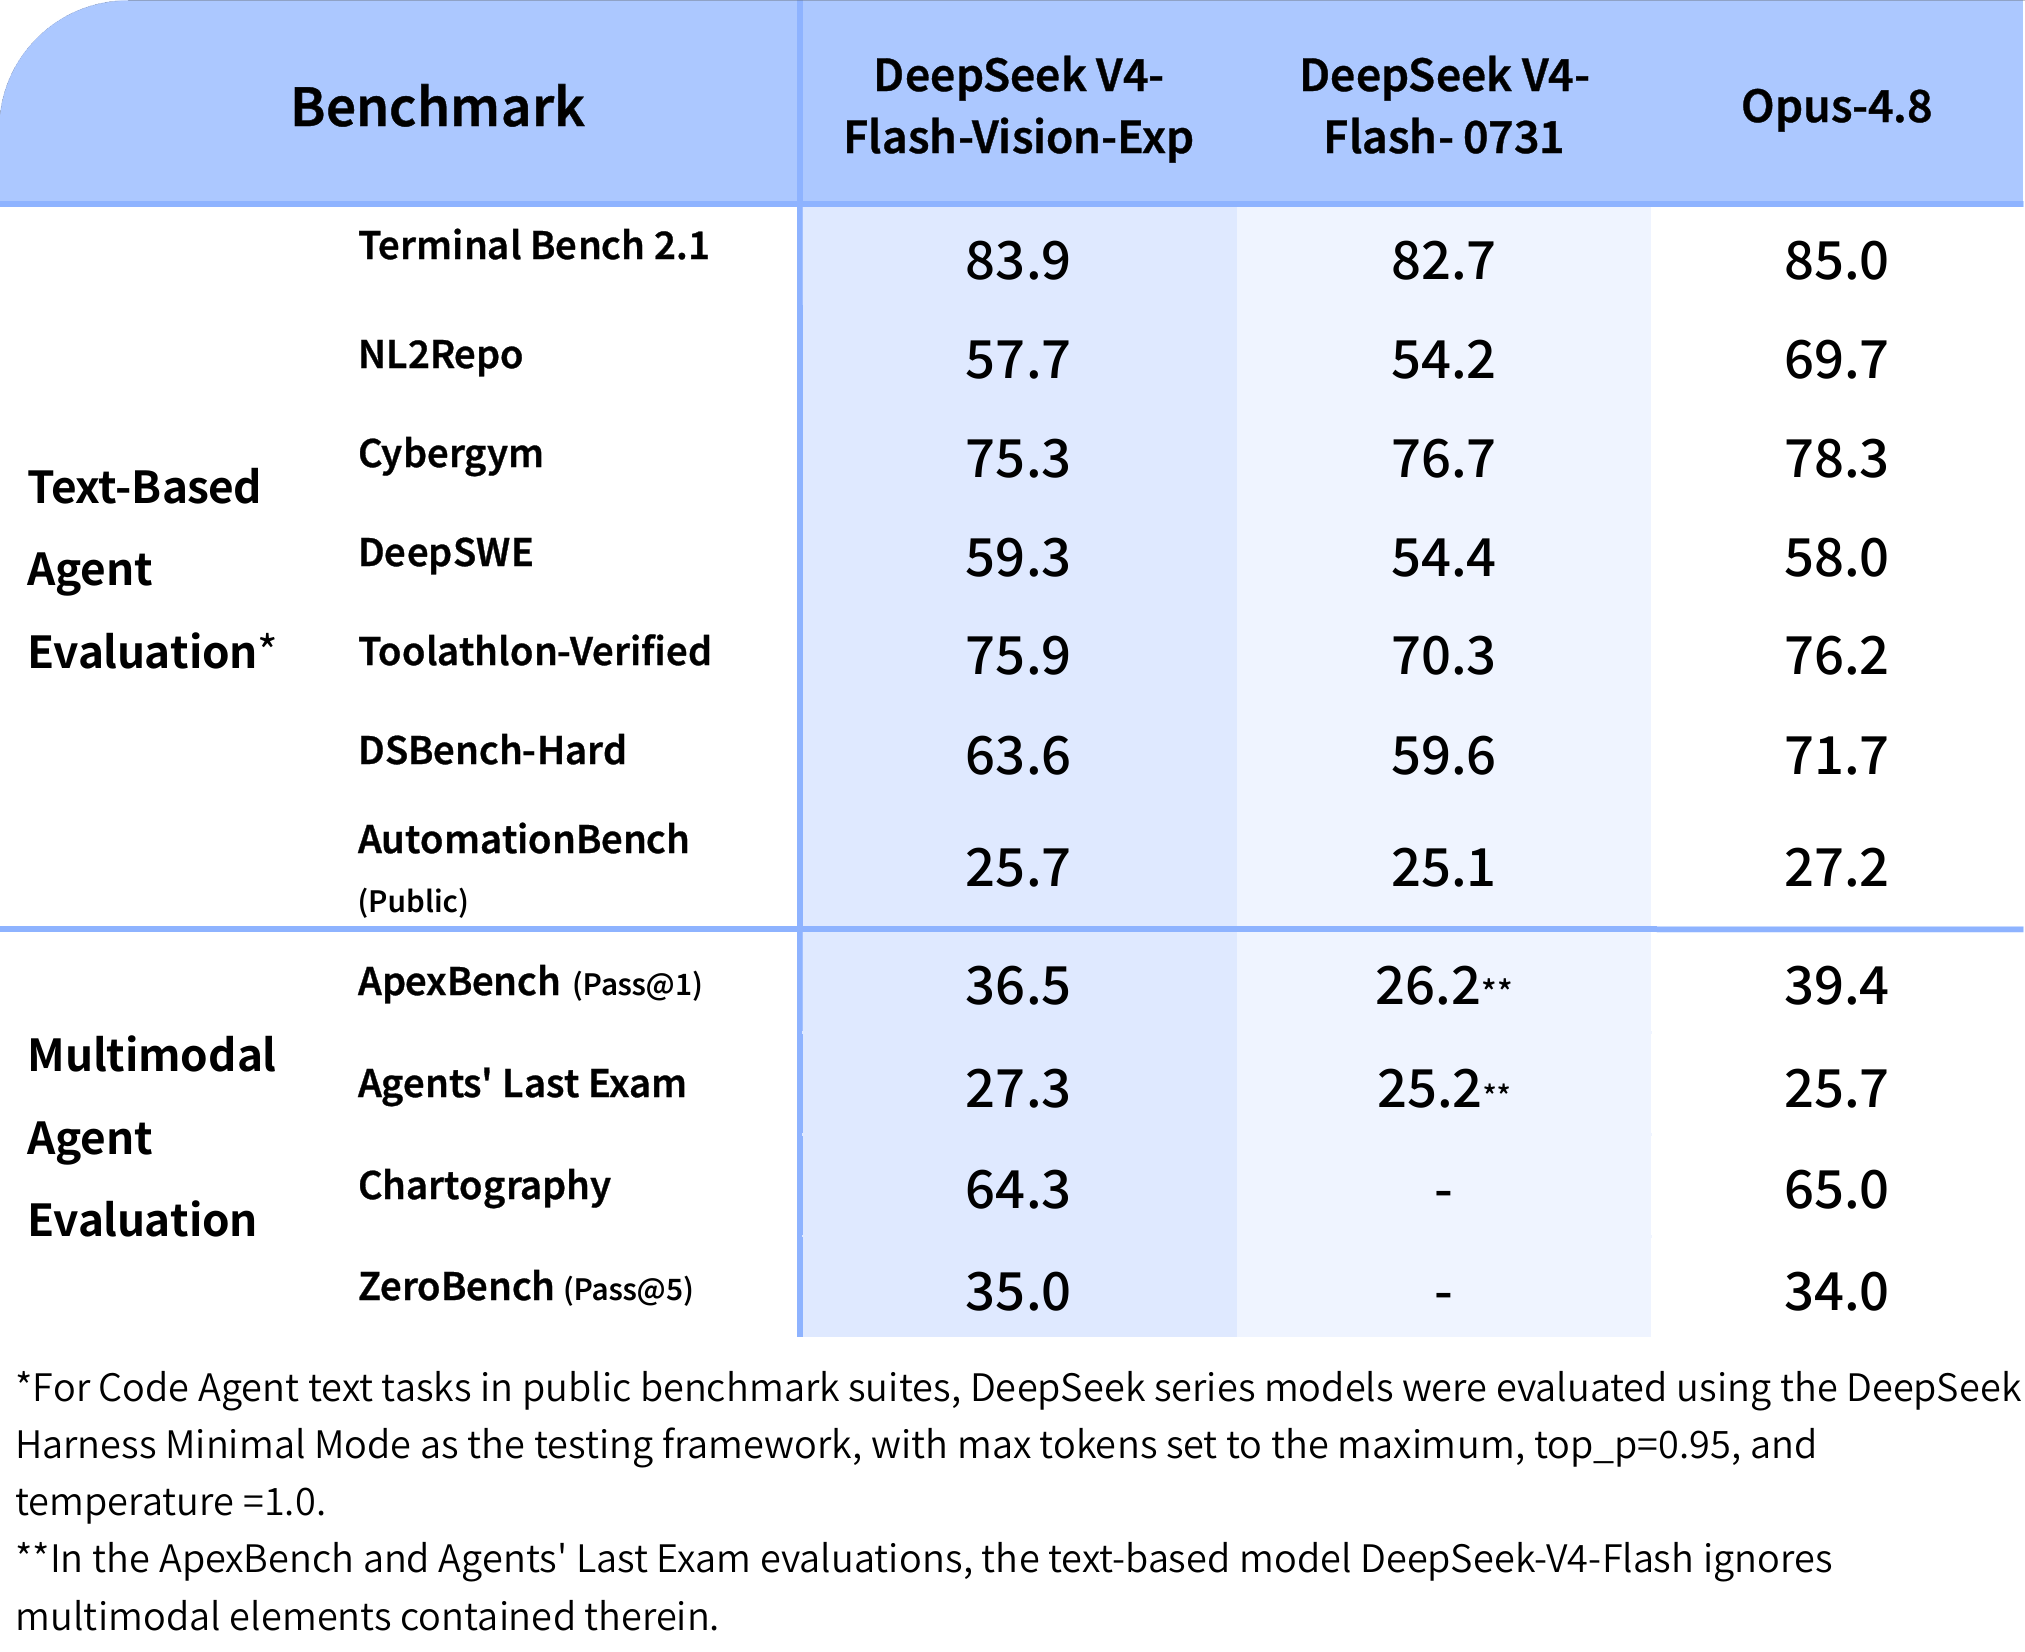
DeepSeek paired the launch with a competitive benchmark claim. On ApexBench, a multimodal agent benchmark, the company reported a score of 36.5 Pass@1 for the new model against 39.4 for Anthropic’s Claude Opus 4.8. That number carries a heavy caveat: DeepSeek evaluated the model with its own internal Harness Minimal Mode, and the results have not been independently verified. A vendor’s benchmark run on its own harness is a marketing figure until outside labs reproduce it.
Alongside the model, DeepSeek made its Files API free, letting developers upload an image once and reference it by ID across requests through the Chat Completions, Messages and Responses APIs. Images are tokenized at up to 384 tokens each and billed at standard V4-Flash pricing, with support for common formats and up to 600 images per request.
The release continues DeepSeek’s pattern of shipping capable models cheaply and measuring them against the frontier labs. Whether V4-Flash-Vision-Exp holds up outside DeepSeek’s own harness — and whether “experimental” graduates to a stable release — will determine how much the Opus comparison is worth.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
