Zero-Shot Text-Guided Object Generation with Dream Fields
Dream Fields can generate the geometry and color of a wide range of objects without 3D supervision. It combines neural rendering with multi-modal image and text representations to synthesize diverse 3D objects solely from natural language descriptions. Take a look!
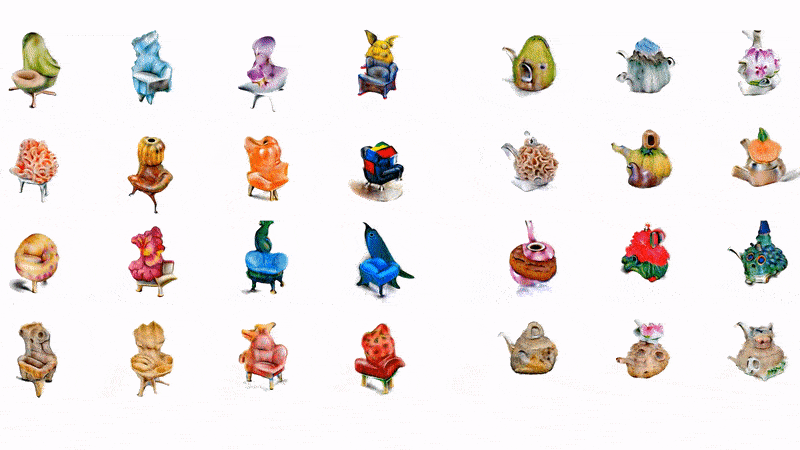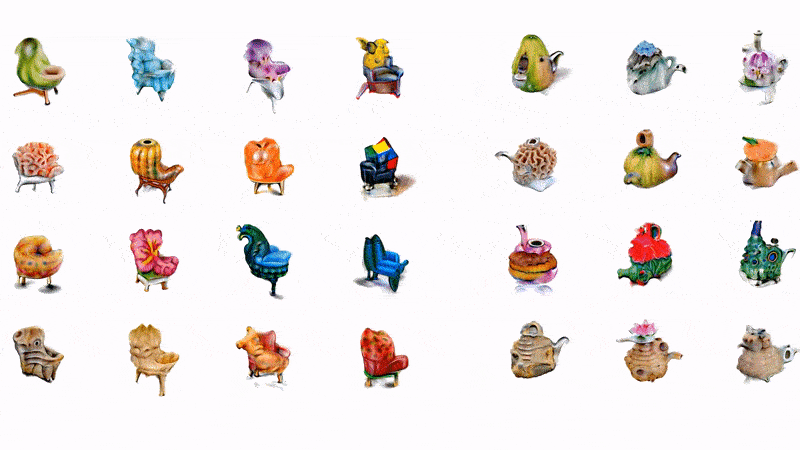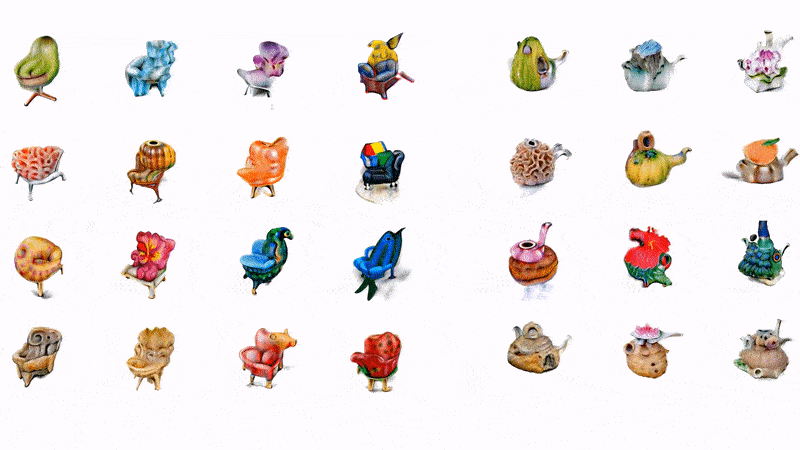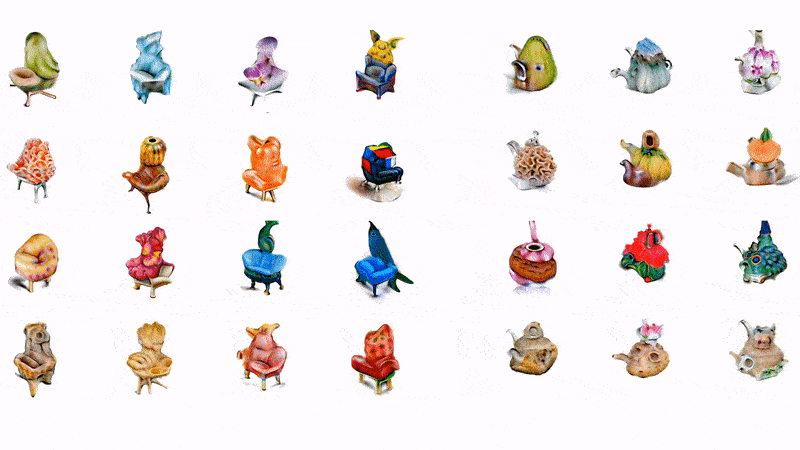
Abstract
We combine neural rendering with multi-modal image and text representations to synthesize diverse 3D objects solely from natural language descriptions. Our method, Dream Fields, can generate the geometry and color of a wide range of objects without 3D supervision. Due to the scarcity of diverse, captioned 3D data, prior methods only generate objects from a handful of categories, such as ShapeNet. Instead, we guide generation with image-text models pre-trained on large datasets of captioned images from the web. Our method optimizes a Neural Radiance Field from many camera views so that rendered images score highly with a target caption according to a pre-trained CLIP model. To improve fidelity and visual quality, we introduce simple geometric priors, including sparsity-inducing transmittance regularization, scene bounds, and new MLP architectures. In experiments, Dream Fields produce realistic, multi-view consistent object geometry and color from a variety of natural language captions.
Video

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024