InstantAvatar: Learning Avatars from Monocular Video in 60 Seconds
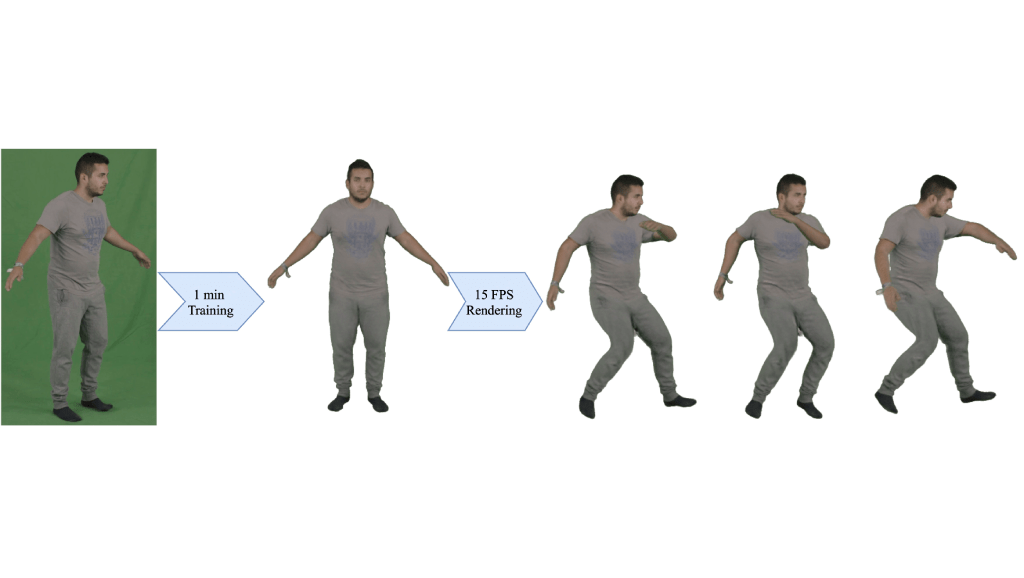
InstantAvatar is a system that can reconstruct human avatars from a monocular video within seconds, and these avatars can be animated and rendered at an interactive rate. It converges 130x faster and can be trained in minutes instead of hours, way faster than competitors.
Abstract
In this paper, we take a significant step towards real-world applicability of monocular neural avatar reconstruction by contributing InstantAvatar, a system that can reconstruct human avatars from a monocular video within seconds, and these avatars can be animated and rendered at an interactive rate. To achieve this efficiency we propose a carefully designed and engineered system, that leverages emerging acceleration structures for neural fields, in combination with an efficient empty space-skipping strategy for dynamic scenes. We also contribute an efficient implementation that we will make available for research purposes. Compared to existing methods, InstantAvatar converges 130x faster and can be trained in minutes instead of hours. It achieves comparable or even better reconstruction quality and novel pose synthesis results. When given the same time budget, our method significantly outperforms SoTA methods. InstantAvatar can yield acceptable visual quality in as little as 10 seconds training time.
Video

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024