AgileAvatar: Stylized 3D Avatar Creation via Cascaded Domain Bridging
AgileAvatar is a novel self-supervised learning framework to create high-quality stylized 3D avatars with a mix of continuous and discrete parameters. To ensure the discrete parameters are optimized, a cascaded relaxation-and-search pipeline is implemented.
Abstract
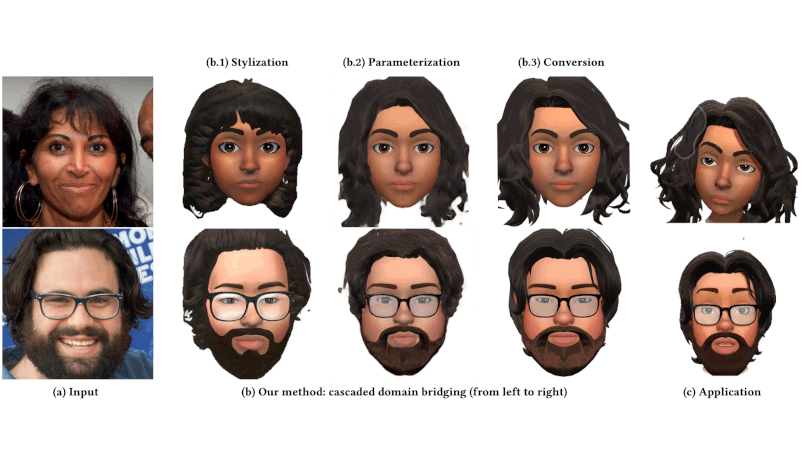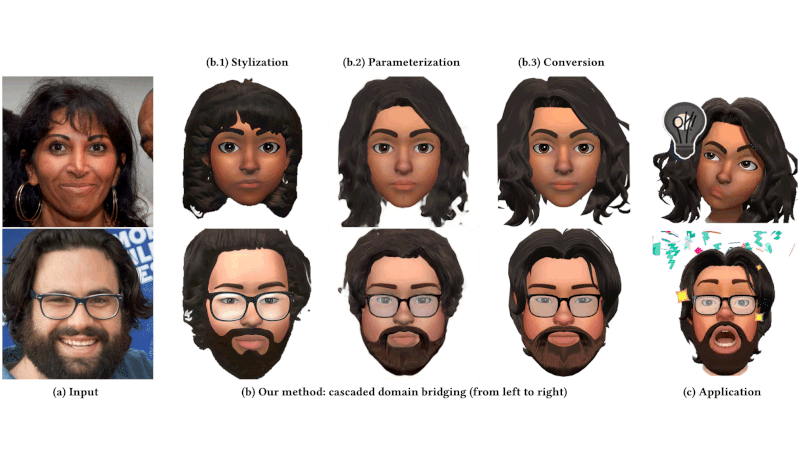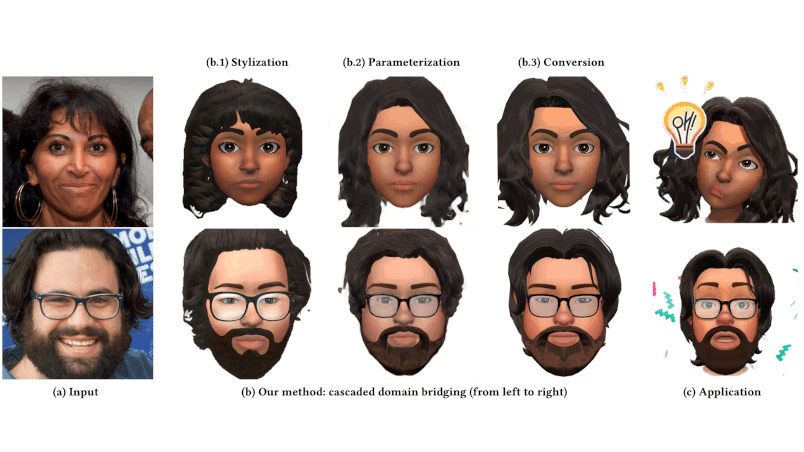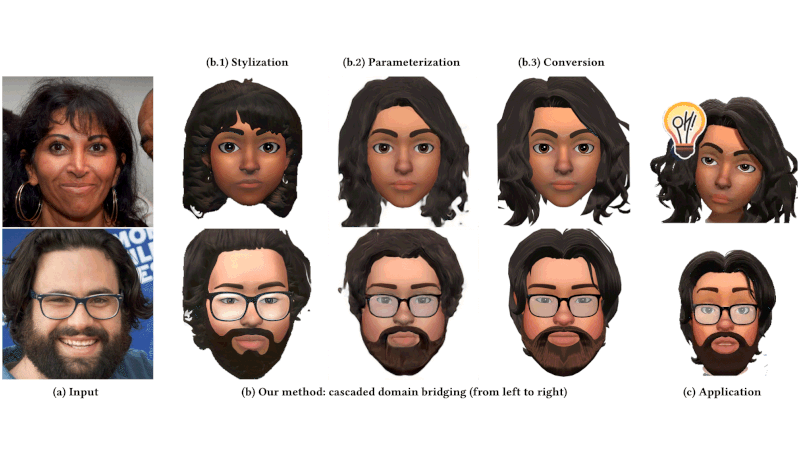
Stylized 3D avatars have become increasingly prominent in our modern life. Creating these avatars manually usually involves laborious selection and adjustment of continuous and discrete parameters and is time-consuming for average users. Self-supervised approaches to automatically create 3D avatars from user selfies promise high quality with little annotation cost but fall short in application to stylized avatars due to a large style domain gap. We propose a novel self-supervised learning framework to create high-quality stylized 3D avatars with a mix of continuous and discrete parameters. Our cascaded domain bridging framework first leverages a modified portrait stylization approach to translate input selfies into stylized avatar renderings as the targets for desired 3D avatars. Next, we find the best parameters of the avatars to match the stylized avatar renderings through a differentiable imitator we train to mimic the avatar graphics engine. To ensure we can effectively optimize the discrete parameters, we adopt a cascaded relaxation-and-search pipeline. We use a human preference study to evaluate how well our method preserves user identity compared to previous work as well as manual creation. Our results achieve much higher preference scores than previous work and close to those of manual creation. We also provide an ablation study to justify the design choices in our pipeline.
Video

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
Continue reading

YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World boosts YOLO with open-vocabulary detection via vision-language modeling, pre-training on large datasets. Efficiently detects objects zero-shot, outperforming state-of-the-art in accuracy and speed.
Dmytro Spodarets·Feb 12, 2024
OMG-Seg: Is One Model Good Enough For All Segmentation?
OMG-Seg is One Model that is Good enough to efficiently and effectively handle all the segmentation tasks, including image semantic, instance, and panoptic segmentation, as well as their video counterparts, open vocabulary settings, prompt-driven, interactive segmentation.
Dmytro Spodarets·Feb 8, 2024
InstantID : Zero-shot Identity-Preserving Generation in Seconds
InstantID, powered by diffusion models, offers plug-and-play image personalization in various styles using one facial image, ensuring high fidelity. It demonstrates remarkable efficiency and performance, making it highly beneficial for applications requiring identity preservation.
Dmytro Spodarets·Feb 5, 2024