NVIDIA launches PAIR beta to distribute local AI inference across home PCs
NVIDIA released a beta of PAIR, or Personal AI Router, software that sends AI inference requests to compatible computers on the same local network. The company said partner RTX Spark Windows PCs are due in October 2026.
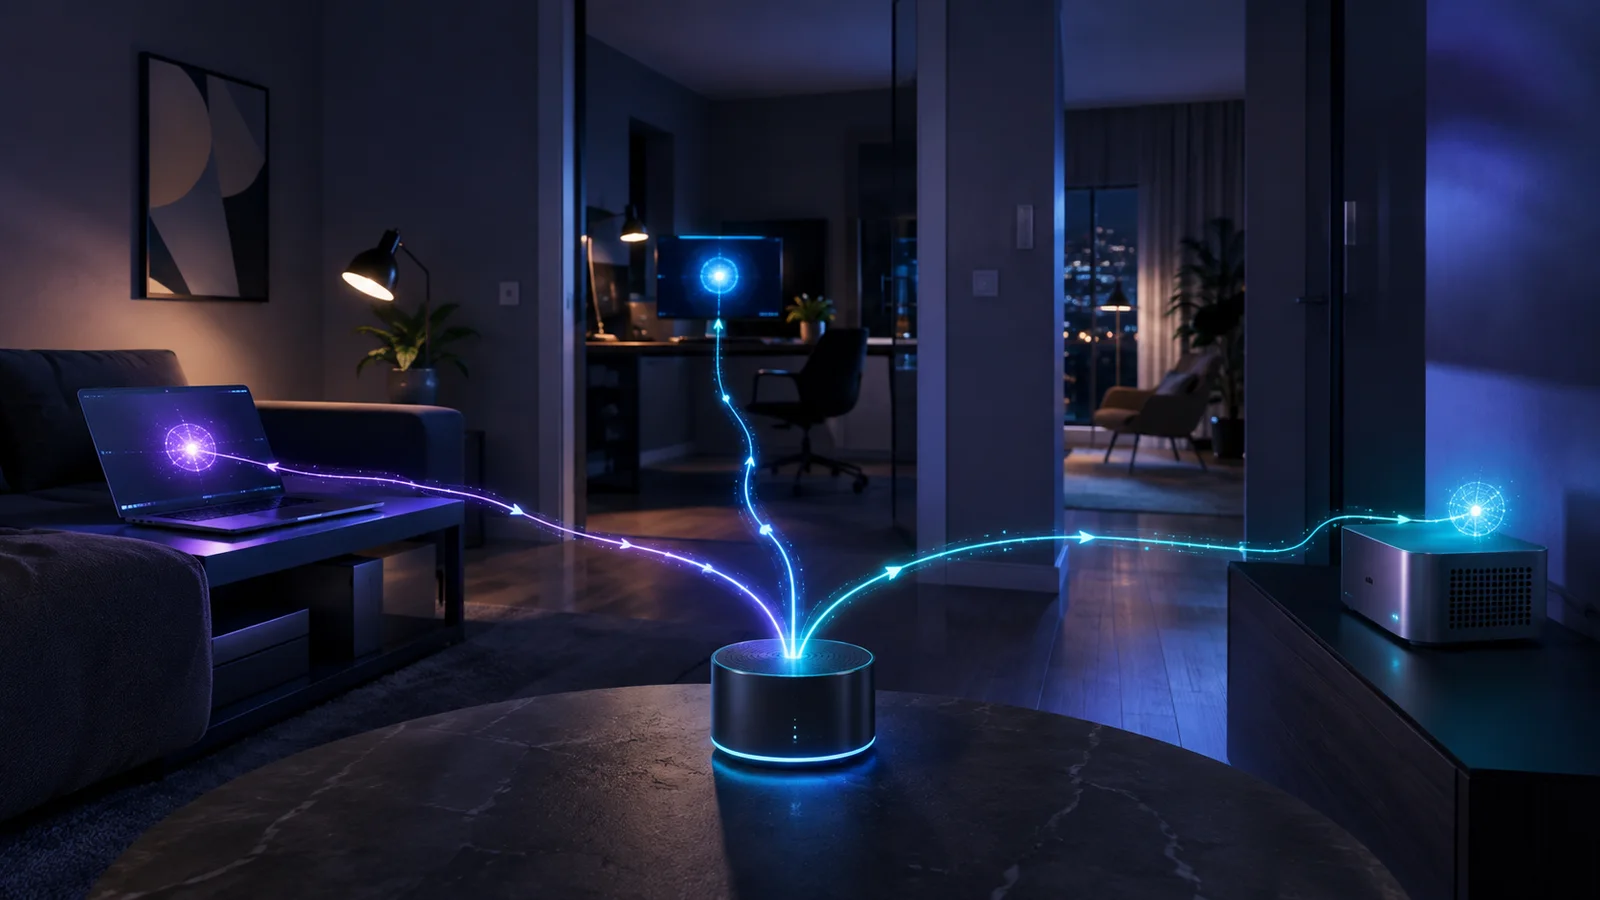
NVIDIA released a beta of PAIR, short for Personal AI Router, software that routes AI inference requests to compatible computers on the same local network. The company introduced it at IFA 2026 on September 3, alongside partner RTX Spark Windows PCs it said will arrive in October.
To an application or agent, PAIR looks like a single local endpoint. Behind it, the router sends each independent request to an eligible machine it finds nearby, so a workload such as several parallel agent tasks can run across idle laptops and desktops already on the network rather than on one PC or a cloud inference service.
The beta covers supported Windows, Linux and macOS systems, including GeForce RTX 20 Series and newer GPUs, DGX Spark, and Apple M4 or newer hardware, subject to inference-engine and model requirements, according to NVIDIA.
Each request runs from start to finish on one selected node. PAIR does not pool GPU memory, combine GPUs into a single virtual GPU, shard a model, or split an in-flight request across machines. In its technical explanation of the router, NVIDIA called that workload-level concurrency: the software distributes separate requests rather than running one request across several GPUs.
Machines find each other over mDNS, a local-network protocol that lets devices discover one another without a central server. NVIDIA said PAIR then picks a destination for each new request based on node readiness, inference-engine status, model availability, current jobs and GPU utilization.
The router exposes Ollama and LM Studio interfaces, so compatible agent workflows can use it without adopting a new cluster API. The release extends NVIDIA’s work on routing AI workloads, which also includes a router for multi-agent AI systems.
The source code is published under the NVIDIA organization on GitHub and identified as Apache-2.0 licensed.
In a demonstration NVIDIA described as unofficial and specific to its configuration, a five-subagent workload running Qwen 3.6 35B A3B averaged 18 minutes on a single RTX Spark laptop and 8 minutes 48 seconds on a three-device PAIR cluster. The company said those figures are not a universal benchmark or a promise of linear scaling. No independent measurement of the software’s performance was available.
NVIDIA said the router may help less with highly sequential workloads, single long model calls, and setups where only one node holds the requested model. The announcement does not say how many machines a PAIR cluster can support.
NVIDIA also said PAIR is designed to keep prompts, files, responses and inference traffic on the local network when the configured clients, model sources, engines and nodes are all local. That statement describes the intended design rather than an independently audited privacy or security result.
The RTX Spark Windows PCs due in October include newly shown Acer and Lenovo designs, NVIDIA said. The company did not give an exact shipping date or pricing.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
