Fable 5 tops Cursor's CursorBench 3.1 coding-agent leaderboard as the vendor eval resurfaces
On Cursor's vendor-run CursorBench 3.1 leaderboard, Fable 5 Max scores 72.9% at $18.02 per task, leading 36 tracked model configurations.
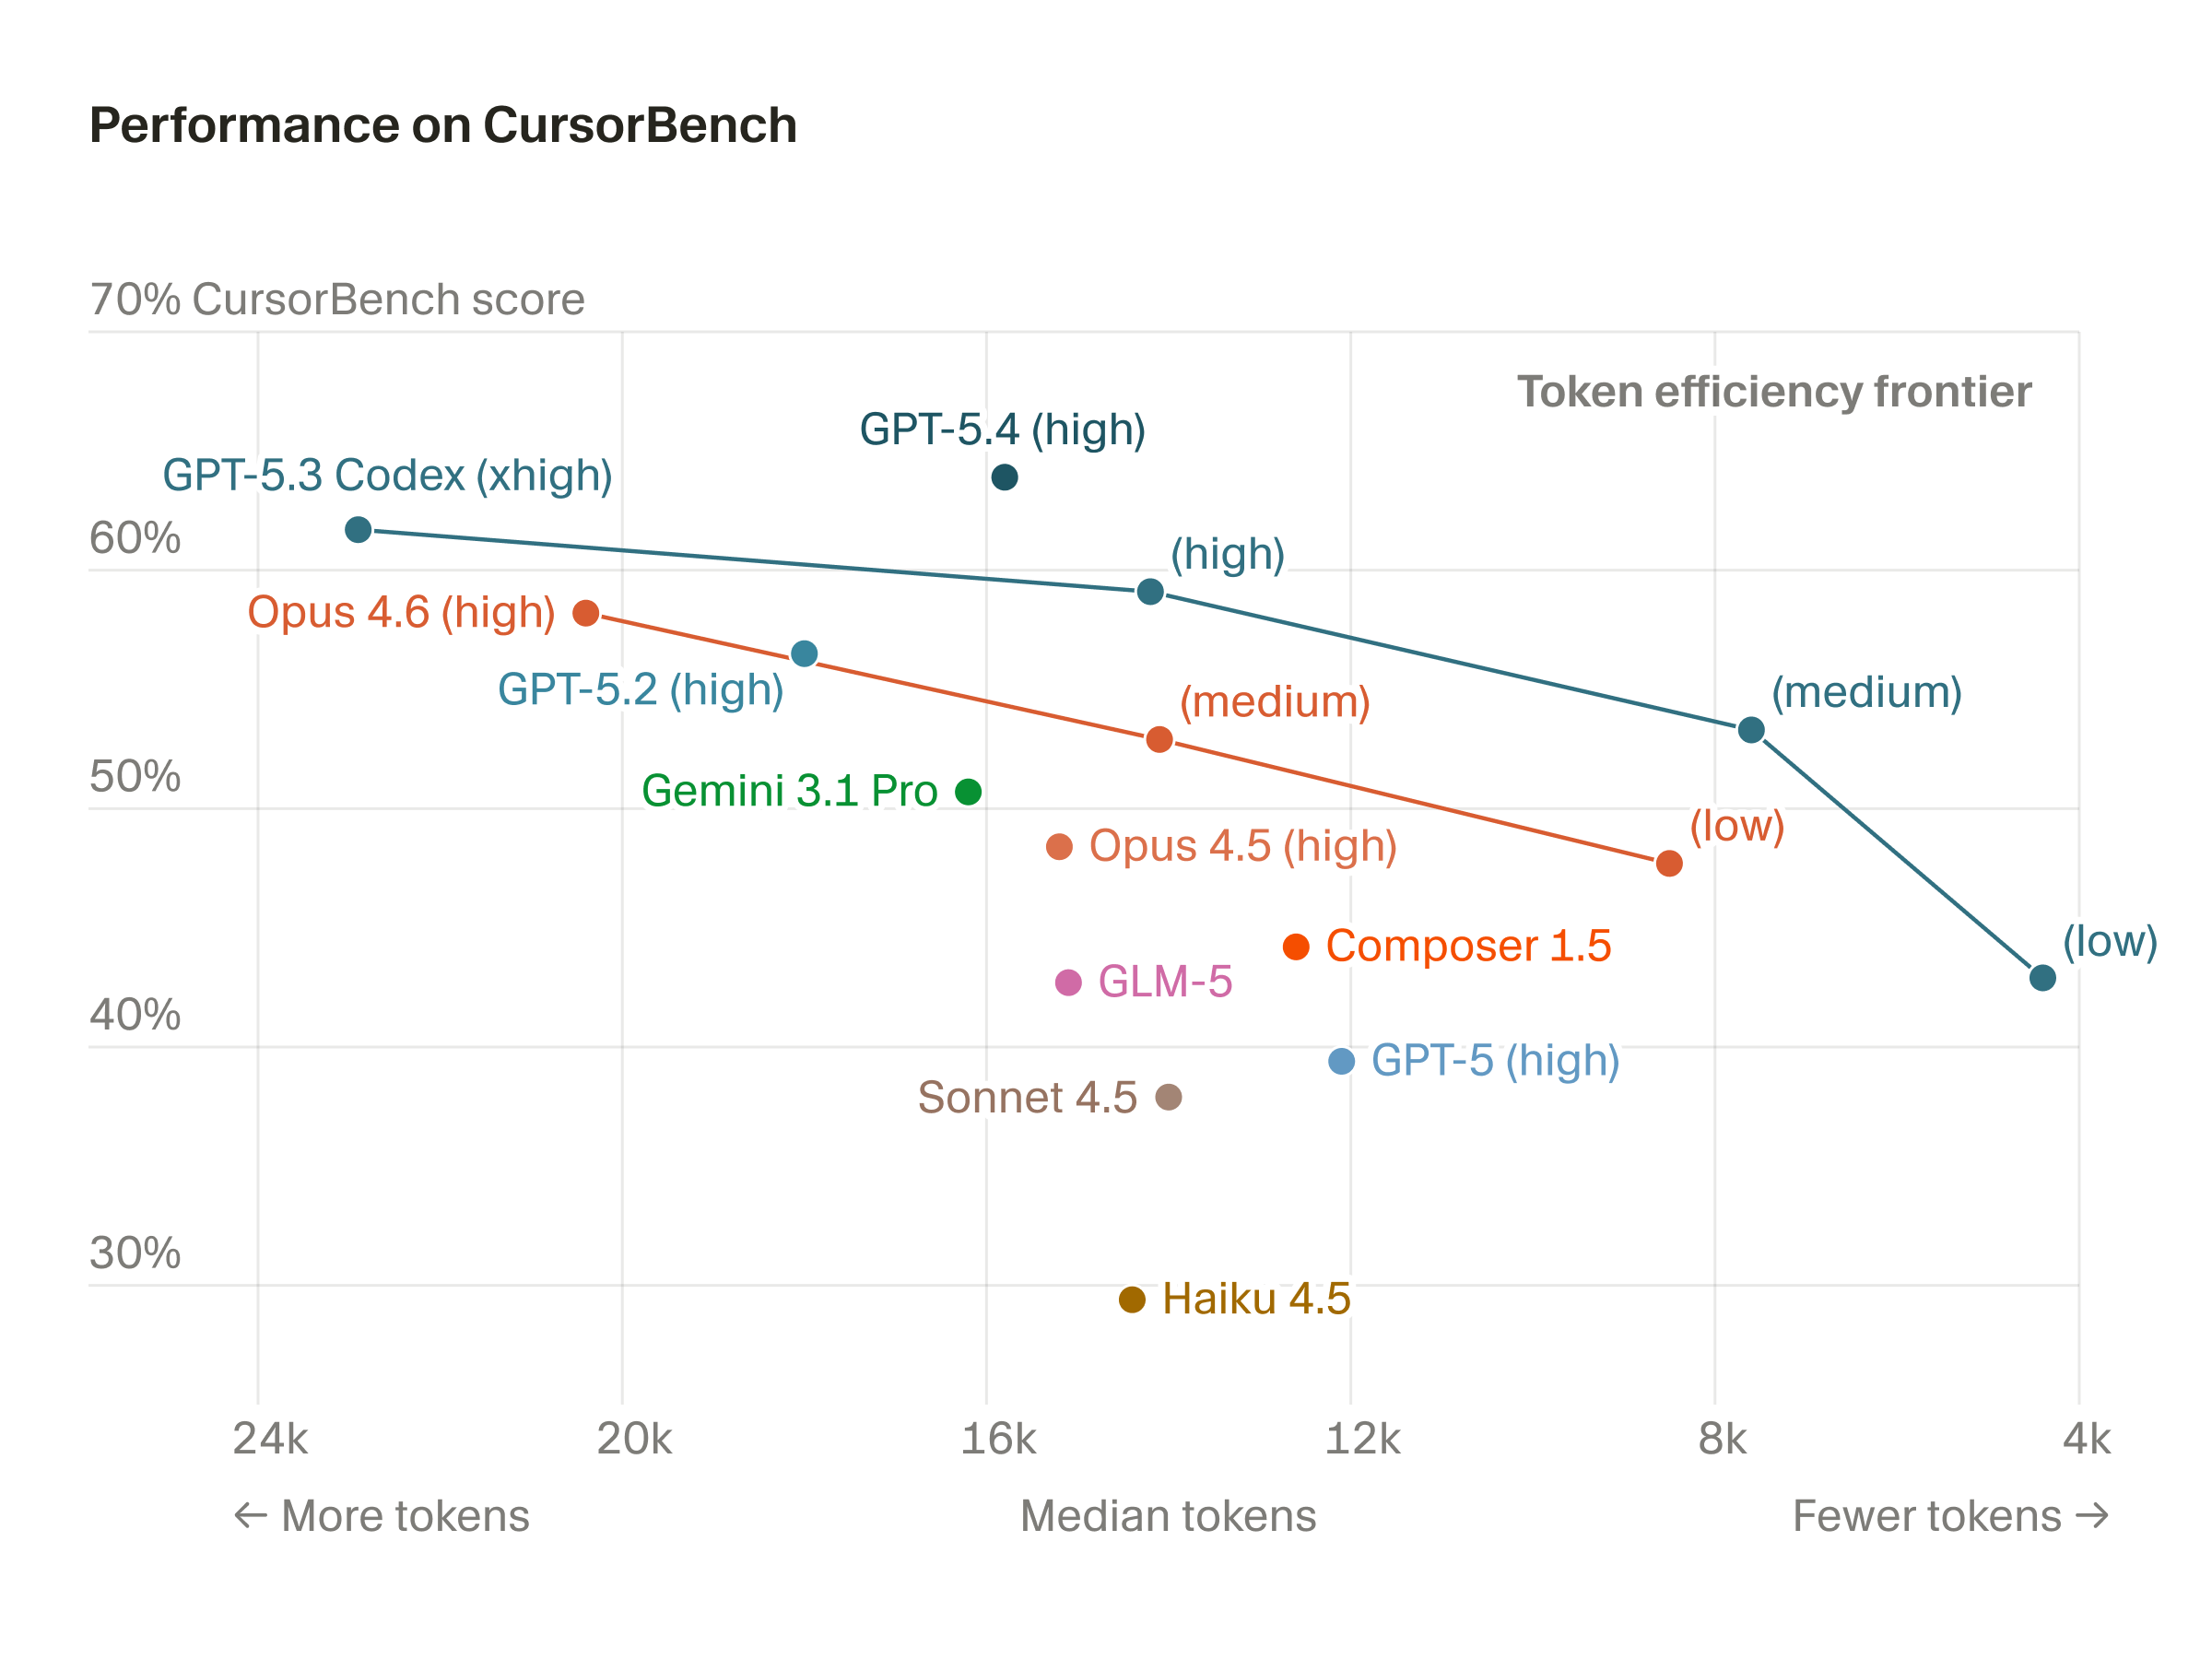
Fable 5 Max tops Cursor’s updated CursorBench 3.1 coding-agent leaderboard, scoring 72.9% at $18.02 per task, the highest of 36 tracked model configurations, according to the AI code editor’s own evaluations page. The benchmark, first published in March, has caught fresh traction as developers revisit it.
That cost-versus-quality tradeoff is what makes the ranking worth a look. CursorBench 3.1 is Cursor’s proprietary, vendor-run evaluation suite that scores AI coding agents on ambiguous, multi-file tasks pulled from real Cursor sessions, using a method the company calls Cursor Blame that traces committed code back to the originating agent request. Version 3.1 added problems on codebase understanding, bug-finding, planning and code review, roughly doubling the scope of the original CursorBench post from March 11.
The caveat is who is grading. This is a vendor-run benchmark from a company that also ships competing models, and Cursor’s own evals page cautions that small score differences “may not be statistically meaningful.”
Below the top line, Fable 5 Extra High scores 72.0% at $13.74 per task, Fable 5 High 70.6% at $10.81, and Fable 5 Medium 69.8% at $8.27. Opus 4.7 Max, from Anthropic, scores 64.8% at $11.02.
Because the scores come from a single vendor on one domain and have not been independently reproduced, they should be read as Cursor’s own measurement, not a settled ranking. The renewed attention has revived comparisons to independent evaluations, and how CursorBench’s numbers hold up against outside benchmarks is the open question.

Founder and Chief Editor of Data Phoenix — a San Francisco Bay Area media and education platform focused on AI and Data.
More news

AWS releases six open-source Hugging Face deployment skills for SageMaker

Google Research releases MilleMiglia logistics benchmark generator

AWS launches AgentCore Runtime V2 with elastic memory and snapshot starts
