AWS introduces cross-Region inference routing for SageMaker HyperPod
AWS lists the managed gateway in 13 Regions and says it can redirect requests from a failing cluster when another eligible cluster serves the requested model.
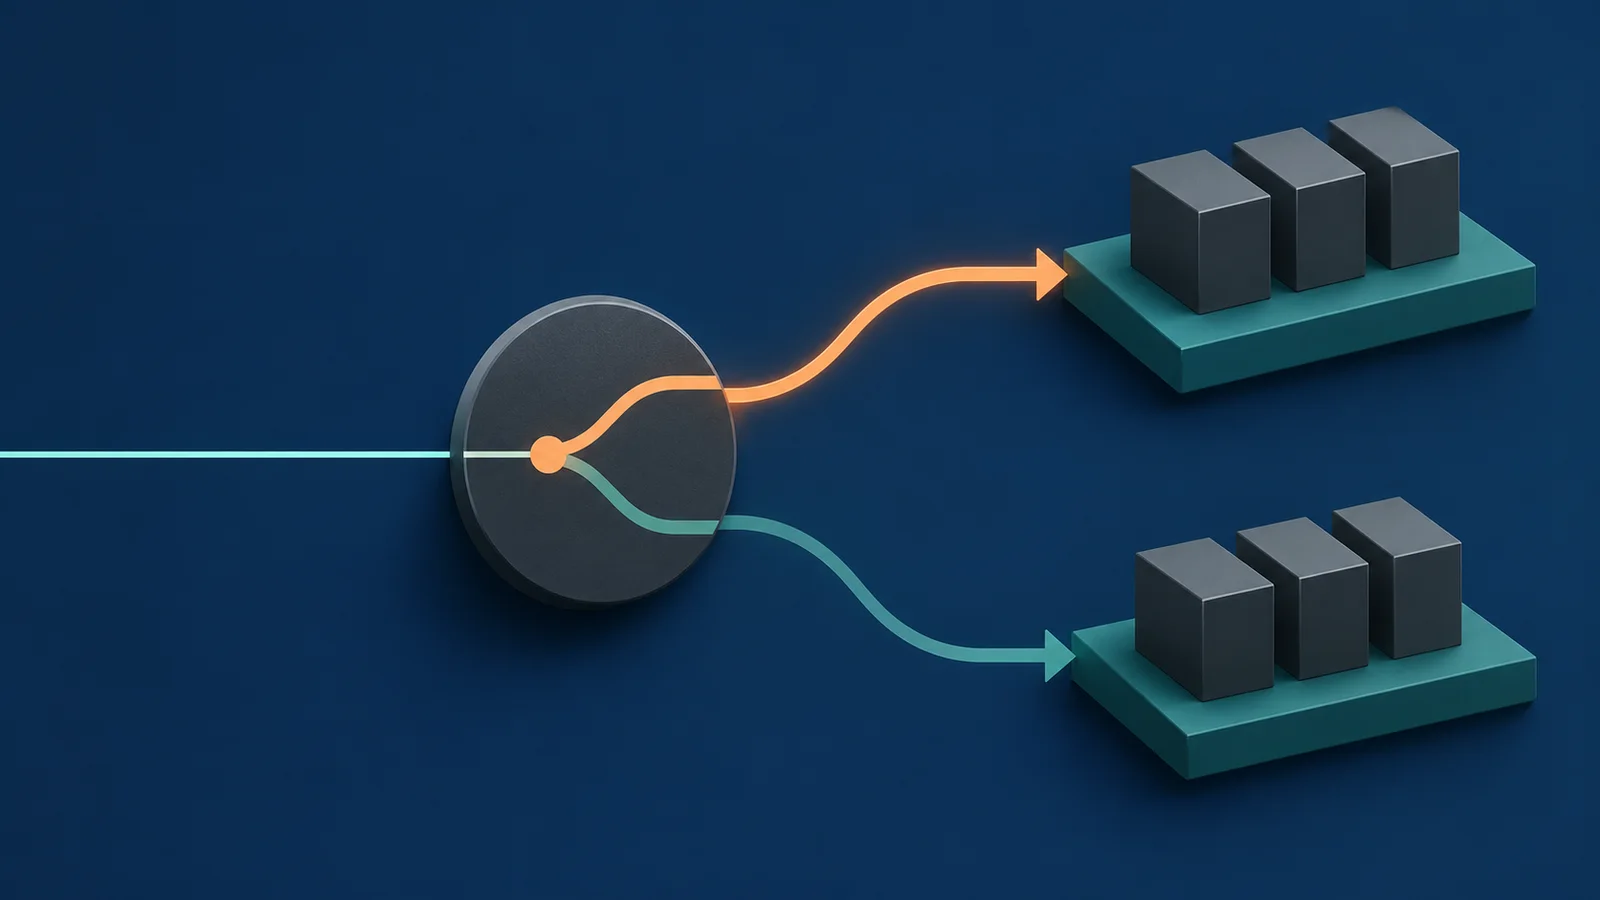
AWS introduced the Amazon SageMaker HyperPod Global Inference Gateway on November 20 and listed it as available in 13 AWS Regions. AWS says customers can send model requests to one managed HTTPS endpoint, which picks an eligible registered HyperPod cluster that serves the requested model in the endpoint’s Region or in another supported Region.
AWS says the gateway shifts traffic away from a failing cluster when another eligible cluster serves the requested model. The company says the gateway can retry an eligible failed request once on another cluster serving the same model, provided the response has not started streaming. If the only cluster serving that model goes down, requests for it fail, AWS says.
AWS says the global gateway ranks eligible clusters by the room left in the cache used to generate responses, the number of requests waiting, whether the cluster is in the endpoint’s Region, and recent request errors. The selected cluster’s own gateway then picks the pod that runs the model, according to AWS.
When AWS introduced the original HyperPod Inference Gateway in September, it described a router that used GPU load signals to direct requests within one cluster. AWS described routing and failover across clusters and Regions as forthcoming.
AWS requires HyperPod clusters orchestrated by Amazon Elastic Kubernetes Service (EKS). Each global gateway supports one to ten registered in-cluster gateways in the same AWS account.
More news
SGLang and Miles add day-zero support for Inkling 2 Mini
VAST Data announces per-job storage controls for VAST AI OS 5.6
AWS adds managed user administration to HyperPod Slurm clusters